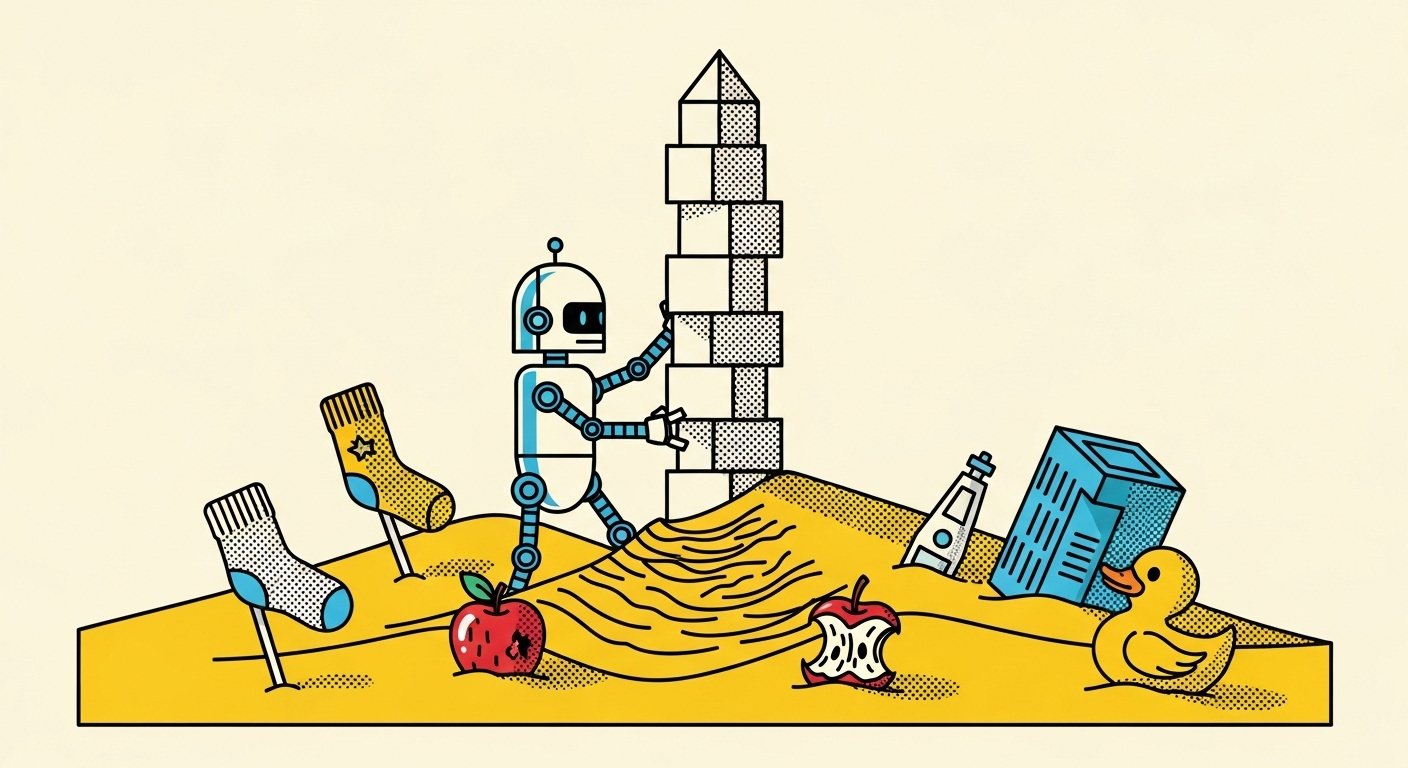
Your AI Is Only As Good As the Data You're Embarrassed to Show Anyone
Enterprise AI fails at the data layer more often than anywhere else. Before a single model is trained, before a vendor is selected, before the board deck is even drafted, most organisations are already building on sand — fragmented datasets, inconsistent labelling, siloed systems that haven't spoken to each other since a middleware project was quietly abandoned in 2019.
The uncomfortable truth is that data readiness is the unglamorous prerequisite that nobody wants to talk about in the roadmap presentation, and the first thing that gets blamed when the AI project doesn't deliver. This article covers what enterprise data readiness actually means, how to audit where you are, and what to fix before you spend another pound on AI tooling.
Why Do So Many Companies Struggle to Get Value From AI?
According to a 2024 study by NewVantage Partners, 74% of firms report they have not yet achieved an AI-ready data culture, despite years of investment in data infrastructure. That's not a technology problem. That's an organisational one.
The pattern I see repeatedly — and I have sat in enough data discovery workshops to have strong feelings about it — is that companies assume AI will somehow impose order on existing chaos. It won't. What it will do is amplify whatever is already there, at speed and at scale. If your CRM has three different spellings of a customer's name and four conflicting records of their last purchase, your AI will confidently and helpfully use all of them.
The model doesn't know it's wrong. That's the bit that keeps people up at night.
What Is Enterprise Data Readiness — And Why Does It Matter for AI?
Data readiness refers to the degree to which an organisation's data is sufficiently clean, structured, accessible, governed, and contextually labelled to support reliable AI and machine learning outputs.
It is not the same as having "a lot of data." Volume is arguably the least interesting dimension. Enterprises frequently have enormous quantities of data that is effectively useless for AI purposes — duplicated, unstructured, ungoverned, and stored in systems that were never designed to talk to anything external.
The three dimensions that actually matter are:
- Quality: Is the data accurate, consistent, and complete?
- Accessibility: Can the right systems reach the right data at the right time?
- Governance: Do you know where the data came from, who changed it, and whether you're legally allowed to use it?
Miss any one of these, and you're not deploying AI. You're deploying very confident guesswork.
What Happens When You Train AI on Bad Data?
Model hallucinations and data drift
Hallucinations — where a large language model (LLM) generates plausible-sounding but factually incorrect outputs — are frequently blamed on the model itself. Often, the real culprit is the data it was fine-tuned on, or the retrieval-augmented context it's drawing from at runtime.
Feed an LLM inconsistent product descriptions, outdated pricing, or contradictory policy documents, and it will do what LLMs do: synthesise a confident answer from conflicting inputs. That answer will be wrong. It will sound right. And someone will act on it.
Data drift is a related problem: the phenomenon where a model's real-world inputs begin to diverge from the data it was trained on. A model trained on pre-2023 customer behaviour will gradually become less accurate as purchasing patterns shift. Without continuous monitoring, you won't know this is happening until the outputs become visibly, expensively wrong.
Biased outputs from biased inputs
This one is less discussed in polite company, but it's a board-level risk. If historical data reflects historical biases — in hiring decisions, credit scoring, customer segmentation — the model will learn those biases and reproduce them at scale. Systematically. Automatically. With a lovely dashboard showing it's working perfectly.
Under the EU AI Act (which I cover in more detail in a separate piece in this series), certain AI applications classified as high-risk require demonstrable bias auditing. "We trained it on our existing data" is not a defence that will satisfy a regulator.
The Hidden Costs of Siloed and Unstructured Data
Most enterprise data problems aren't dramatic. They're mundane. And that's precisely what makes them so persistent.
The sales team's CRM doesn't match the finance team's billing system. The operations database uses different product codes from the ERP. Customer records exist in five places and are authoritative in none of them. Nobody set out to create this situation. It accumulated, one integration shortcut at a time, over fifteen years of organic growth and three mergers.
The cost of this isn't just an AI problem. According to Gartner, poor data quality costs organisations an average of $12.9 million per year. But AI makes the cost visible in a way that nothing else does, because AI systems will attempt to use every piece of data you give them, and the outputs will reflect the quality of what they consumed.
The specific failure modes to watch for
- Volume mismatches: Training a model on insufficient labelled examples for a specific domain, then wondering why it underperforms in production.
- Label inconsistency: Human-annotated training data where different annotators applied different standards — common in document classification and sentiment analysis tasks.
- Stale reference data: Look-up tables and taxonomies that haven't been updated since someone who understood them left the organisation.
- Shadow data: Datasets living in individual spreadsheets, personal drives, or departmental databases that IT doesn't know exist — and that are definitely being used somewhere.
How Do You Actually Audit Enterprise Data Readiness?
A data readiness audit is not a technical exercise wearing a business hat. It's a business exercise that requires technical execution. The goal is to understand what data you have, what condition it's in, and whether it can support the specific AI use cases you're planning. Not data in general. Those specific use cases.
The sequence I use with clients follows four stages:
Stage 1: Inventory and discovery
Map every significant data source in the organisation. This includes formal systems (ERP, CRM, HRIS, data warehouses) and informal ones (shared drives, email archives, third-party SaaS exports). The informal ones are usually where the surprises are.
Stage 2: Quality assessment
For each source, assess completeness (are required fields populated?), consistency (do values align across systems?), accuracy (do records reflect reality?), and timeliness (how current is the data?). Automate this where you can; manual spot-checking where you can't.
Stage 3: Governance and lineage review
Data lineage — the documented history of where data came from and how it's been transformed — is non-negotiable for AI deployments in regulated industries. If you cannot explain where a piece of data originated, you cannot confidently use it to train or inform a model that will influence decisions about customers, finances, or operations.
Stage 4: Gap analysis against AI use case requirements
This is where the audit becomes actionable. Map the data quality requirements of your intended AI applications against what you actually have. The gaps are your remediation roadmap. Be honest about this. I have seen gap analyses where the gap was essentially "everything," and the right answer in that situation is to delay the AI deployment, not to proceed and hope.
What Does "A Single Source of Truth" Actually Mean in Practice?
Every data strategy document written since 2015 mentions a "single source of truth." Very few organisations have achieved one. This is not because the concept is wrong; it's because the implementation requires sustained organisational will that outlasts the enthusiasm of the initiative that spawned it.
In practical terms, a single source of truth for AI purposes means:
- A canonical data model that defines how key entities (customers, products, transactions) are represented across systems
- Clear data ownership — a named person or team responsible for the quality and governance of each domain
- A unified data platform (whether a data lakehouse, a federated query layer, or a well-governed data warehouse) that provides consistent access without requiring every team to maintain their own copy
- API-first integration between operational systems, so data doesn't need to be manually extracted and re-entered to move between them
This is not a weekend project. It is, however, the foundation without which enterprise AI will produce exactly the kind of results that make boards question whether they should have spent the money on something else.
Data Readiness vs. AI Maturity: Where Does Your Organisation Sit?
| Maturity Level | Data Characteristics | AI Capability | Primary Risk |
|---|---|---|---|
| Level 1 – Fragmented | Siloed systems, manual exports, no governance | Basic reporting only; no reliable ML | AI outputs are confidently wrong |
| Level 2 – Consolidated | Data warehouse exists; quality inconsistent | Descriptive analytics; limited predictive | Model drift goes undetected |
| Level 3 – Governed | Defined ownership, lineage documented, quality monitored | Reliable ML in specific domains | Scaling across domains is slow |
| Level 4 – Unified | Real-time streams, canonical model, automated quality checks | Enterprise-wide AI deployment; LLM fine-tuning | Governance can't keep pace with velocity |
| Level 5 – Adaptive | Self-monitoring data pipelines; continuous quality feedback loops | Agentic AI; autonomous workflows | Human oversight becomes the bottleneck |
Most mid-market enterprises I work with sit somewhere between Level 1 and Level 2, while presenting a Level 4 strategy to their board. That gap is where AI projects go to quietly expire.
How Do You Implement Automated Data Quality Monitoring?
Manual data quality checks are better than nothing, in the same way that checking your tyre pressure by kicking the tyre is better than nothing. It's not a strategy.
Automated data quality monitoring involves deploying tooling that continuously validates data against defined rules, flags anomalies, and alerts the appropriate owner before corrupted data reaches a model. The key components are:
- Schema validation: Ensuring incoming data conforms to the expected structure and data types
- Statistical drift detection: Monitoring for shifts in data distributions that might indicate a source system change or data corruption
- Referential integrity checks: Confirming that relationships between datasets remain valid (e.g., every transaction record has a corresponding valid customer ID)
- Completeness thresholds: Automated alerts when the proportion of null or missing values in critical fields exceeds an acceptable tolerance
- Lineage tracking: Maintaining an auditable record of every transformation applied to data as it moves through pipelines
Tools in this space include Great Expectations, Monte Carlo, Soda, and the data observability capabilities built into platforms like Databricks and dbt. The specific tooling matters less than the discipline of actually implementing and acting on the alerts.
What About Unstructured Data — Documents, Emails, and Audio?
The conversation about data readiness tends to focus on structured data — rows and columns, databases, clean CSVs. But a significant proportion of enterprise knowledge exists in formats that resist easy processing: PDFs, email threads, call recordings, meeting transcripts, scanned contracts, presentation decks.
This is where the promise of LLMs becomes genuinely compelling, and where the risk becomes genuinely acute. A retrieval-augmented generation (RAG) system — where an LLM draws on a corpus of internal documents to answer questions — is only as trustworthy as the documents in that corpus.
If your internal documentation is contradictory, outdated, or contains information that should never leave a specific context (HR records, legally privileged communications, commercially sensitive pricing), a poorly governed RAG deployment will find it, use it, and potentially surface it in a context that causes significant problems.
Preparing unstructured data for AI use requires:
- A content inventory — knowing what documents exist and where
- Classification and sensitivity tagging — understanding what can and cannot be used
- Chunking and embedding strategies that preserve context rather than fragmenting it arbitrarily
- Version control — ensuring the model draws on current documents, not superseded ones
The Relationship Between Data Readiness and AI Governance
Data readiness and AI governance are not the same thing, but they are inseparable. A governance framework that doesn't address data quality, lineage, and access control is governance in name only.
Under the EU AI Act, high-risk AI systems must be trained on data that is "relevant, sufficiently representative, and to the best extent possible, free of errors." That's a regulatory obligation with financial consequences, not a best-practice recommendation. It requires documented evidence of data quality processes — not an assertion that the data is probably fine.
I cover the full governance and compliance picture in a separate article in this series. The point here is that the data readiness work you do now is also your compliance foundation. Do it once, document it properly, and it serves both purposes.
Frequently Asked Questions
How long does a data readiness audit take for an enterprise organisation?
Realistically, a thorough data readiness audit for a mid-market enterprise takes between four and twelve weeks, depending on the number of systems, the complexity of integrations, and how well-documented the existing architecture is. Organisations with mature IT governance at the lower end; those discovering their data estate for the first time at the higher end.
Do we need to fix all of our data before starting an AI project?
No — and anyone who tells you otherwise is either being theoretically pure or has never delivered a real project. The pragmatic approach is to identify the specific data required for your highest-priority AI use case and focus remediation there first. You are not trying to boil the ocean; you are trying to make one specific thing work reliably. Then the next thing.
What is the difference between a data lake, a data warehouse, and a data lakehouse?
A data warehouse stores structured, processed data optimised for querying and reporting. A data lake stores raw data in its native format — structured, semi-structured, and unstructured — at lower cost but with less inherent governance. A data lakehouse combines both approaches: the flexibility and scale of a lake with the governance and query performance of a warehouse. For most enterprise AI programmes, the lakehouse architecture (as implemented in platforms like Databricks or Microsoft Fabric) is currently the most practical foundation.
What does "data sovereignty" mean and why does it matter for AI?
Data sovereignty refers to the principle that data is subject to the laws and governance of the country in which it is collected or processed. For AI deployments, training data, model outputs, and inference logs may all constitute data processing under GDPR or equivalent regulations — and using cloud AI services that process data outside your jurisdiction without appropriate safeguards is a compliance risk that is frequently underestimated during vendor selection.
How do we handle data quality when our data comes from third-party sources?
Third-party data introduces risks you cannot fully control, which means you need to manage them contractually and technically. Contractually: ensure data supply agreements include quality standards, update frequencies, and liability clauses. Technically: treat all third-party data as untrusted until validated against your own quality rules, and monitor it continuously for drift or degradation.
Is synthetic data a viable alternative to real data for training AI models?
In specific circumstances, yes. Synthetic data — artificially generated datasets designed to mirror the statistical properties of real data — is increasingly used to augment insufficient training datasets, protect privacy, and test model behaviour in edge cases. It is not a substitute for real-world data in production contexts, and models trained exclusively on synthetic data often exhibit subtle distributional biases that only become apparent when they encounter genuine users. Use it as a supplement, not a shortcut.
Nicholas Hodder is a digital transformation and technology leader with over 20 years of experience delivering enterprise programmes across public, private, and third sectors. He works with boards and executive teams on AI strategy, data governance, and the organisational change required to make technology investments actually pay off.
If your AI programme is stalling and you suspect the data layer is where the real problem lives, get in touch to discuss an Enterprise Data Readiness Audit. It's not the most glamorous conversation to initiate, but it is almost certainly the most useful one you'll have this quarter.